
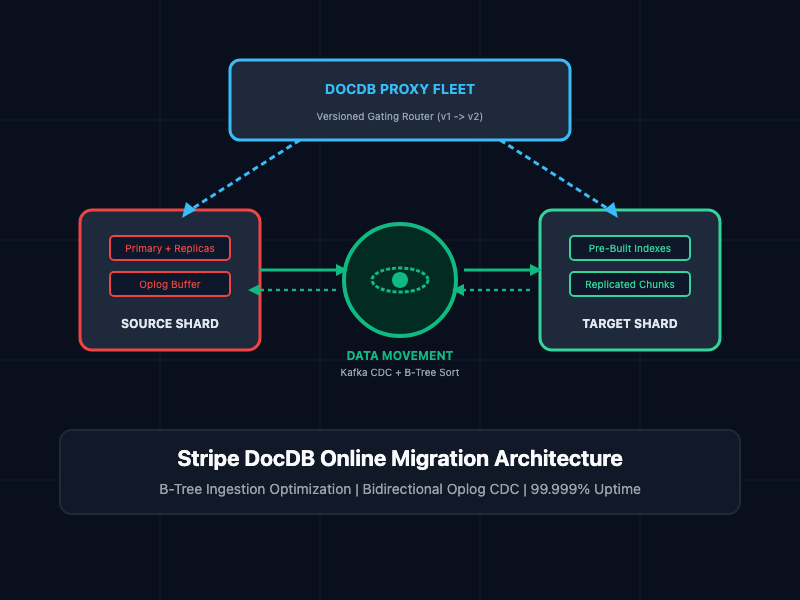
Managing petabyte-scale document databases while maintaining 99.999% availability demands zero-downtime data migrations. Stripe's Data Movement Platform powers DocDB, its internal DBaaS built on MongoDB, enabling online chunk migrations across thousands of shards via B-tree insertion sorting, Kafka-backed CDC oplog replication, and versioned traffic gating. #Stripe #DocDB #ZeroDowntime #DatabaseMigration #SRE #MongoDB #DistributedSystems #DataEngineering #FinOps #HighAvailability
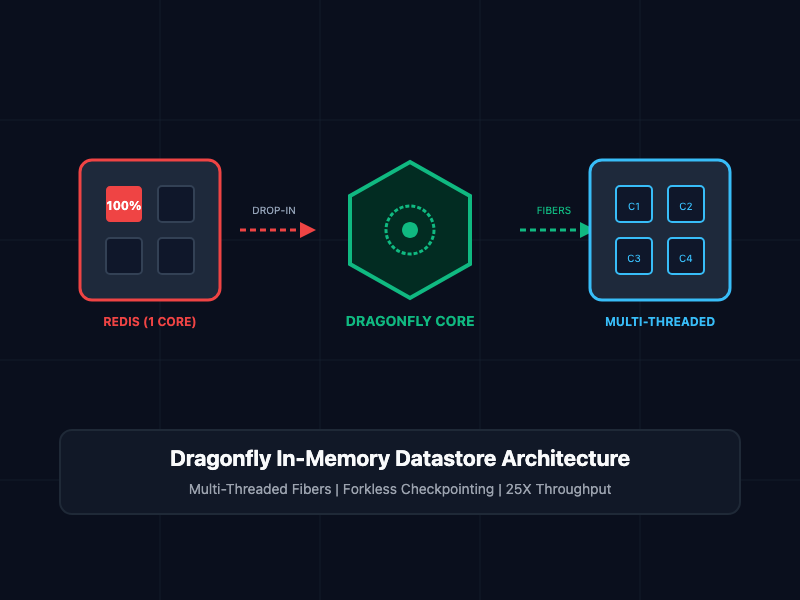
Redis clustering adds operational overhead, while single-threaded bottlenecks limit vertical scaling on multi-core servers. Dragonfly solves this as an ultra-fast, drop-in in-memory datastore replacement for Redis/Memcached, delivering up to 25X higher throughput and 80% lower memory overhead via a multi-threaded shared-nothing fiber architecture. Learn how to deploy Dragonfly with zero code changes. #DragonflyDB #Redis #Memcached #Caching #DevOps #SRE #Database #Backend #FinOps #CloudNative
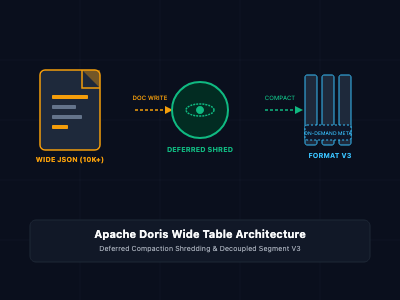
Managing schema-evolving datasets with thousands of dynamic keys presents severe metadata bloat and ingestion bottlenecks. This guide explores how Apache Doris 4.1 solves the wide-JSON problem using DOC mode (deferred JSON shredding) and Storage Format V3 (on-demand metadata loading), delivering columnar performance with the ingestion speed of a document store. #ApacheDoris #WideJSON #DatabaseArchitecture #OLAP #DataEngineering #SRE #BigData #Observability #StorageEngine #VeloDB